Framework overview and why it matters
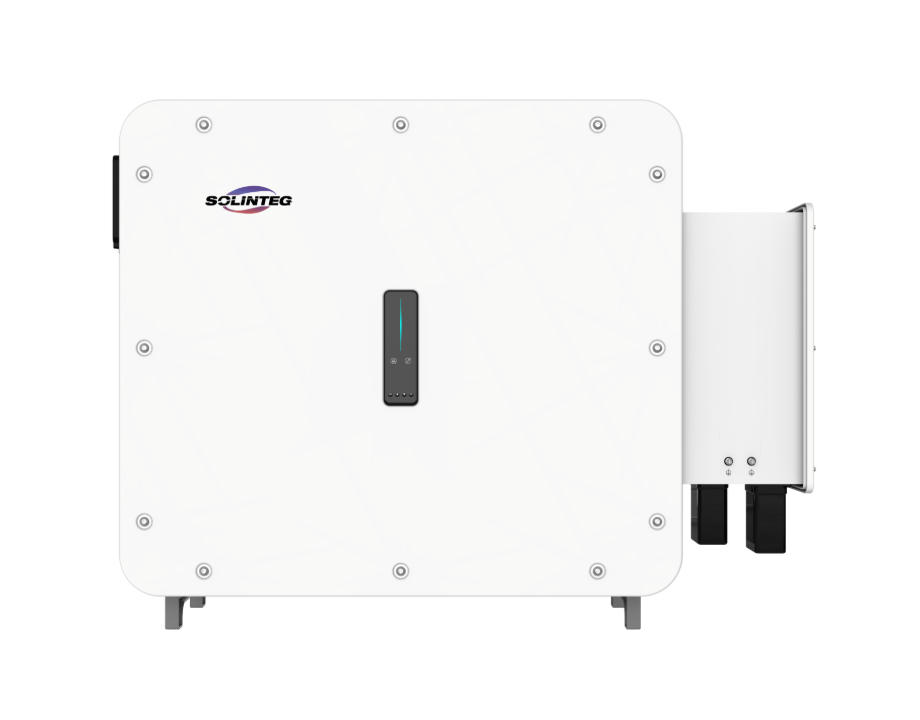
This piece presents a step-by-step maintenance framework tailored to commercial solar installations, focused on predictable outcomes and measurable returns. The approach covers routine checks, component-level controls, and lifecycle monitoring for home energy storage systems adapted to commercial scale. Real-world anchor: the February 2021 Texas grid crisis highlighted how storage and control failures magnify downtime; operators who had robust battery management and local controls fared better. The framework maps to standard components such as BMS, inverters, and thermal management subsystems, and it’s written in plain, technical terms for operations staff and facility managers.

Step 1 — Establish baseline metrics
Record capacity, round-trip efficiency, and average state of charge (SoC) under normal operation. Baseline data lets you detect degradation and validates warranty claims. Use simple logs: daily SoC range, inverter fault count, and cycle count per string. Track {main_keyword} and {variation_keyword} as part of your initial dataset so comparisons remain consistent across vendors and seasons. Calibration of meters and verification of CT/PT accuracy are non-negotiable.
Step 2 — Weekly and monthly checks
Weekly: inspect enclosure integrity, venting, and visible wiring. Monthly: run a health check report from the battery management system (BMS) and confirm firmware parity across modules. Prioritize these readings: cell voltages, temperature gradients, and depth of discharge (DoD) averages. Small anomalies often precede larger failures—address them immediately to avoid forced curtailment during peak demand. It’s simple work, but it matters.
Step 3 — Thermal control and ventilation
Thermal stress shortens cycle life. Maintain HVAC setpoints for battery rooms and verify airflow paths every quarter. Replace filters before they restrict flow. Install redundancy for cooling fans and validate failover sequences during maintenance windows. Temperature imbalance between racks indicates wiring or contact resistance issues that will accelerate aging—fix those fast.
Step 4 — Firmware, inverter tuning, and communications
Keep inverter and BMS firmware current, but stage updates: deploy to a test string before plant-wide rollout. Validate communication links (Modbus, CAN, ethernet) and timestamp alignment for event correlation. A mismatched timestamp or dropped packet can hide root causes and slow diagnostics. Maintain a version control log for firmware and configuration templates.
Step 5 — Predictive monitoring and routine testing
Deploy cycle-life forecasting using historical charge/discharge profiles and measured round-trip efficiency. Schedule capacity verification tests annually or after a major event. Use partial-discharge tests to limit stress while gaining SOH (state of health) insight. Integrate the monitoring feed into the site’s energy management layer so alarms route to responsible technicians without delay.
Common mistakes operators make
Operators often skip basic housekeeping—dusty cabinets, loose lugs, and ignored alarms cause most outages. They also treat firmware updates as optional. Another frequent error is treating all packs the same; cell balancing and SoC windows must be tuned per chemistry and vendor specifications—don’t standardize blindly. Minor point: grounding and surge protection are frequently underspecified in installation documents. Fix those gaps early.
Maintenance playbook — checklist and responsibilities
Use a concise checklist: visual inspection, BMS report extraction, thermal scan, inverter diagnostics, communications test, and spare parts audit. Assign ownership: technician for inspections, engineer for firmware and root-cause, and operations lead for scheduling. Keep parts like fuses, fan modules, and contactors on-site. A short rotation of spares reduces mean time to repair considerably.
Advisory: three golden rules for evaluation
1) Monitor what degrades: prioritize SoH, cycle count, and temperature variance as your three core KPIs. 2) Test conservatively: choose partial-discharge capacity checks that reveal trends without stressing cells. 3) Validate vendor support: confirm response SLAs, spare-part lead times, and firmware documentation before procurement. These rules let you compare designs objectively and protect revenue from unexpected downtime.
Final note
Applied consistently, this framework reduces surprise failures and extends usable cycle life while keeping operations predictable. The technical controls and measures described above align with commercial needs and integrate naturally with a robust home energy management system for centralized visibility and control. Trust programmatic maintenance—measure, act, iterate—and you’ll see measurable uptime improvement. SOLINTEG. –